
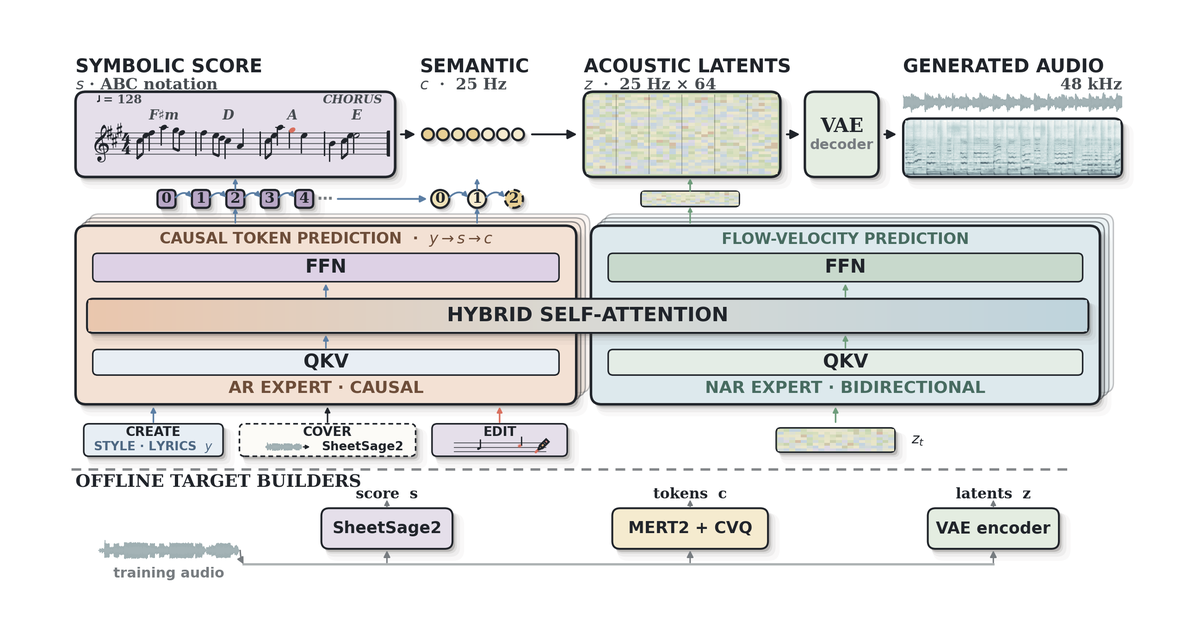
Multimodal Art Projection, with the Hong Kong University of Science and Technology and other partners, released YuE2 on Sept. 9, 2026. The open model writes a melody-and-chord plan in ABC notation, then renders a full song with vocals and accompaniment.
The Hugging Face checkpoint YuE2-3B is listed at about 3.6 billion parameters. The team says one AR-NAR Mixture-of-Transformers backbone predicts the score and semantic tokens, then generates acoustic latents with flow matching. A VAE decodes those latents to 48 kHz stereo audio.
Company claim: on a 24 GB NVIDIA RTX 4090, YuE2 generated a 3.6-minute song in 71 seconds, with a peak of about 11 GiB in the published Hugging Face timings. Maximum-context testing peaked at 14.08 GiB. Weights are licensed CC BY-NC 4.0. Inference code is on GitHub.
The project page says YuE2 was trained primarily on CC0 music and licensed synthetic data, about 346,000 hours, with Tokenwave.AI providing most of the synthetic set. Partners listed on the official page include NYU, Stanford, MBZUAI, NOIZ and ACE Studio.
Lab-reported WildSongBench results, updated Sept. 12, 2026, put YuE2 best-of-8 at 6.9632 on SongBench, ahead of Suno v5 at 6.8721 and Suno v6 at 6.5562 in that comparison. The team notes the comparison uses different selection budgets. Those scores are automatic, team-run measures, not an independent listening test.
The technical report is listed as coming soon. The team says to cite the 2025 YuE paper for now. Treat quality, legal and method claims as lab statements until the report and independent tests exist.
Ground Truth, writing Sept. 11, 2026, describes the score-first design, the non-commercial license, and the same 71-second RTX 4090 timing. GIGAZINE dated the release Sept. 10, 2026, and described YuE2 as close to paid Suno 5, including when selecting the best of eight tracks.