
Desk
Discover
-
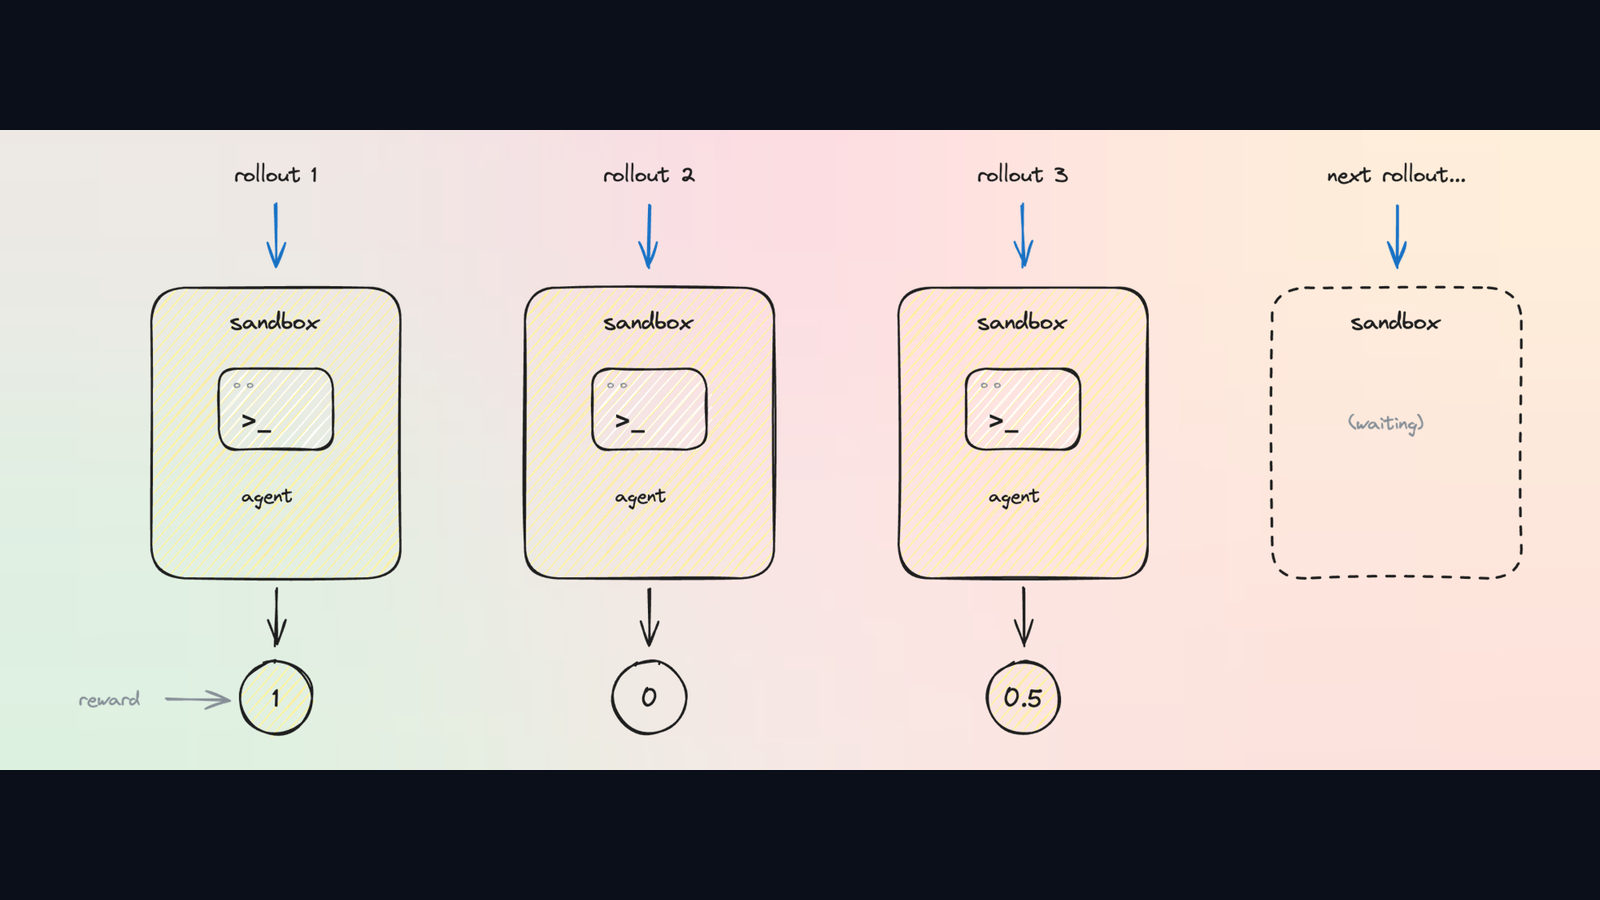
Hugging Face survey maps one-sandbox-per-rollout pattern across 13 agent labs
On Sept. 11, 2026, Hugging Face published a survey of 15 reports from 13 labs arguing agentic RL now needs a dedicated sandbox per rollout. Cursor, SemiAnalysis, E2B/Paper Instruments, and Modal independently describe the same concurrency and state pattern.
-
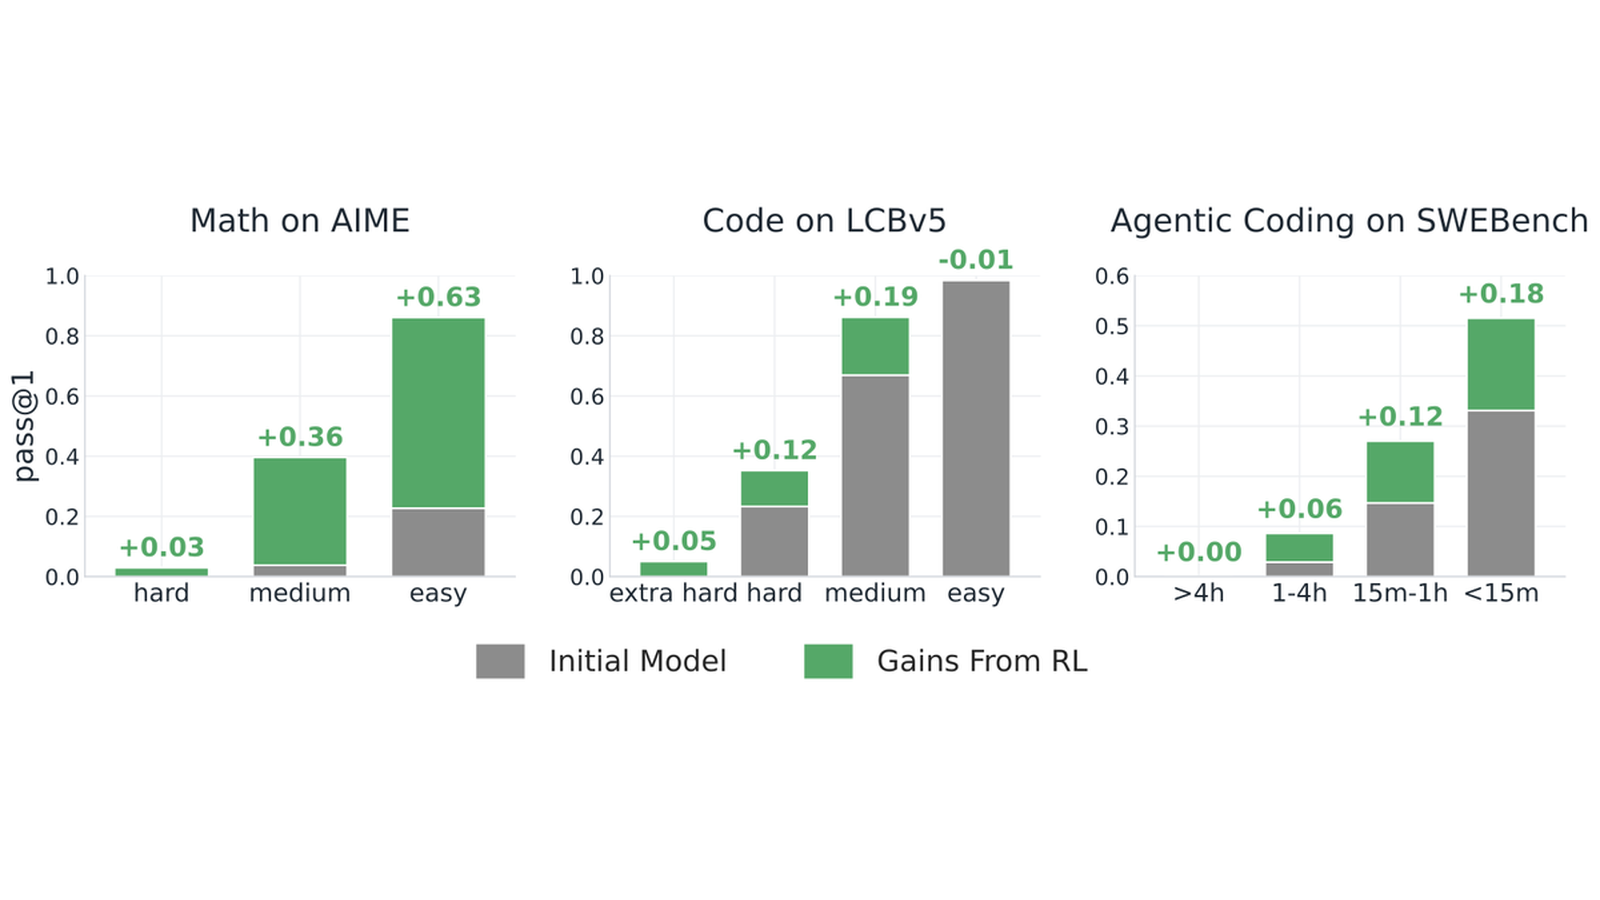
Mila preprint maps Matthew Effect in RL for LLMs and proposes Never Give Up
A Mila and Université de Montréal arXiv preprint from Sept. 11, 2026, argues RL for LLMs improves easy problems far more than hard ones (the Matthew Effect) and proposes Never Give Up adaptive sampling; Deepscaler and Manufactoria figures are author claims, and linked code remained 404 as of Sept. 16.
-
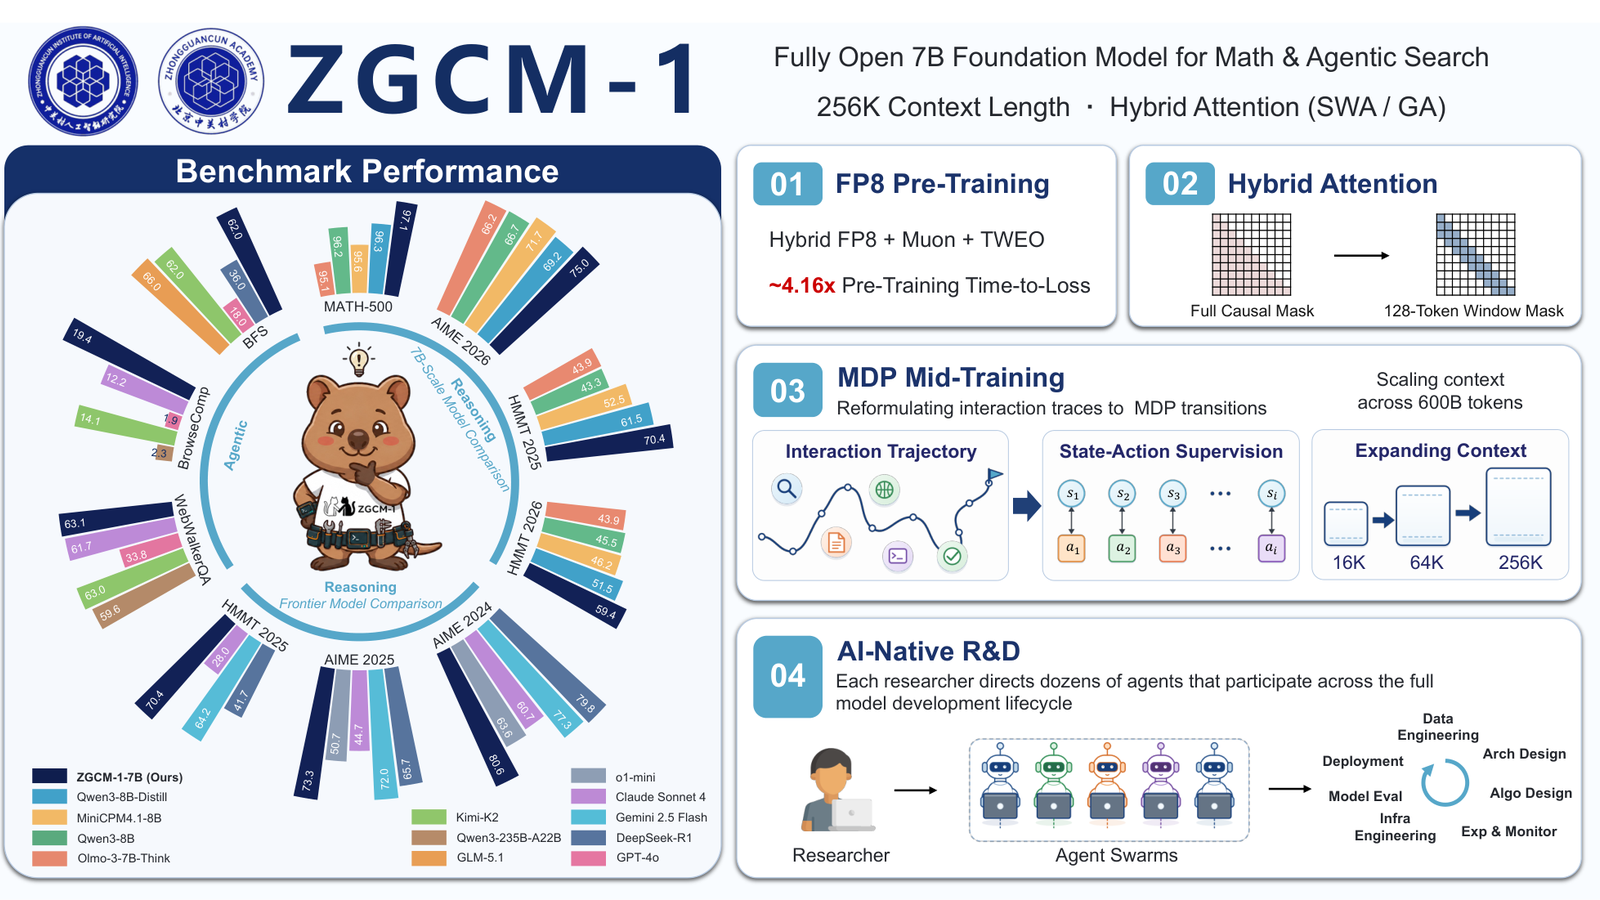
Zhongguancun Academy opens ZGCM-1 for math and agentic search
On Sept. 11, 2026, Zhongguancun Academy and the Zhongguancun Institute of Artificial Intelligence released ZGCM-1, a fully open 7.39B dense model trained from scratch for math and agentic search with 256K context. Author and Hugging Face card scores, including MATH-500, AIME, HMMT, WebWalkerQA, and a ~4.2x training-efficiency figure, remain company claims; Beckmann and CCTest covered the openness without independent bench replication.
-
DeepSeek ships V4.1-Flash as an open multimodal model as API docs keep V4-Pro live
DeepSeek released DeepSeek-V4.1-Flash on Sept. 10, 2026, as API id deepseek-flash with MIT weights, native image input, and a 1 million-token context. After the Sept. 14 cutover window, live pricing and changelog say V4-Pro continues with billing unchanged, while the launch page still shows a superseded route-to-Flash line.
-
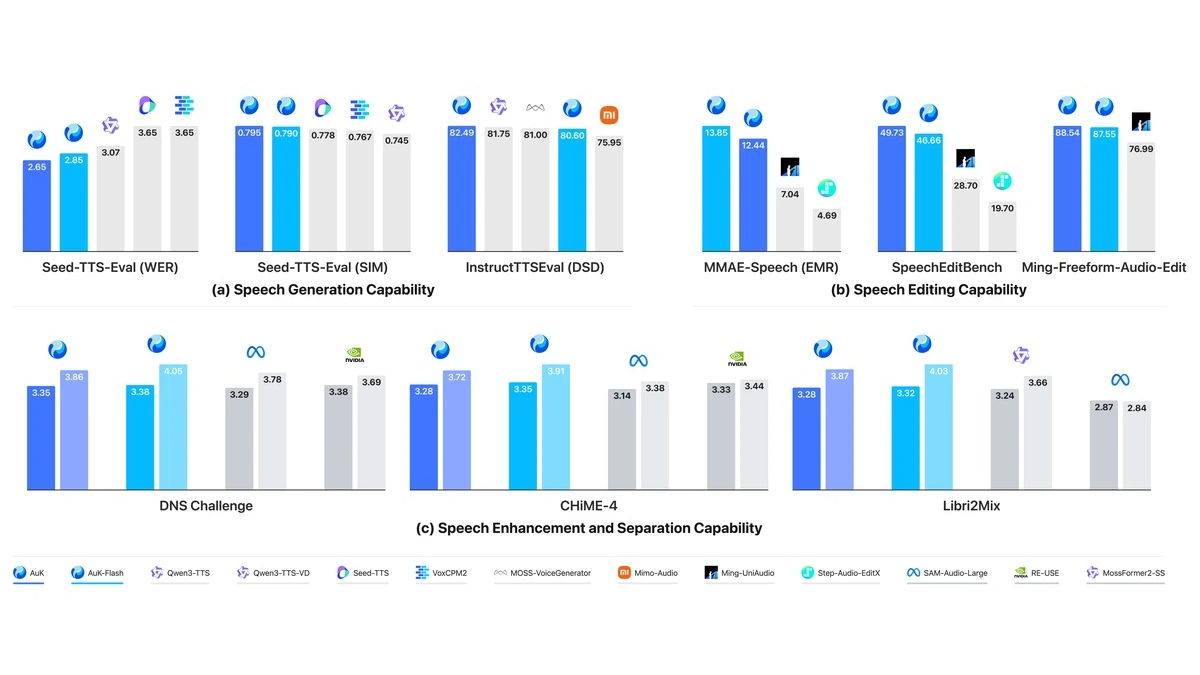
Tencent open-sources AuK, a 1.5B model for instruction-guided speech generation and editing
Tencent Hunyuan released AuK and distilled AuK-Flash on Sept. 9, 2026, with MIT weights on Hugging Face and ModelScope and a technical report on arXiv (2609.08936). The 1.5B flow backbone unifies zero-shot and instruct TTS, content and acoustic edits, paralinguistic edits, enhancement, and separation behind natural-language instructions. Vendor tables lead several generation and editing benchmarks; independent reproduction is still missing.
-
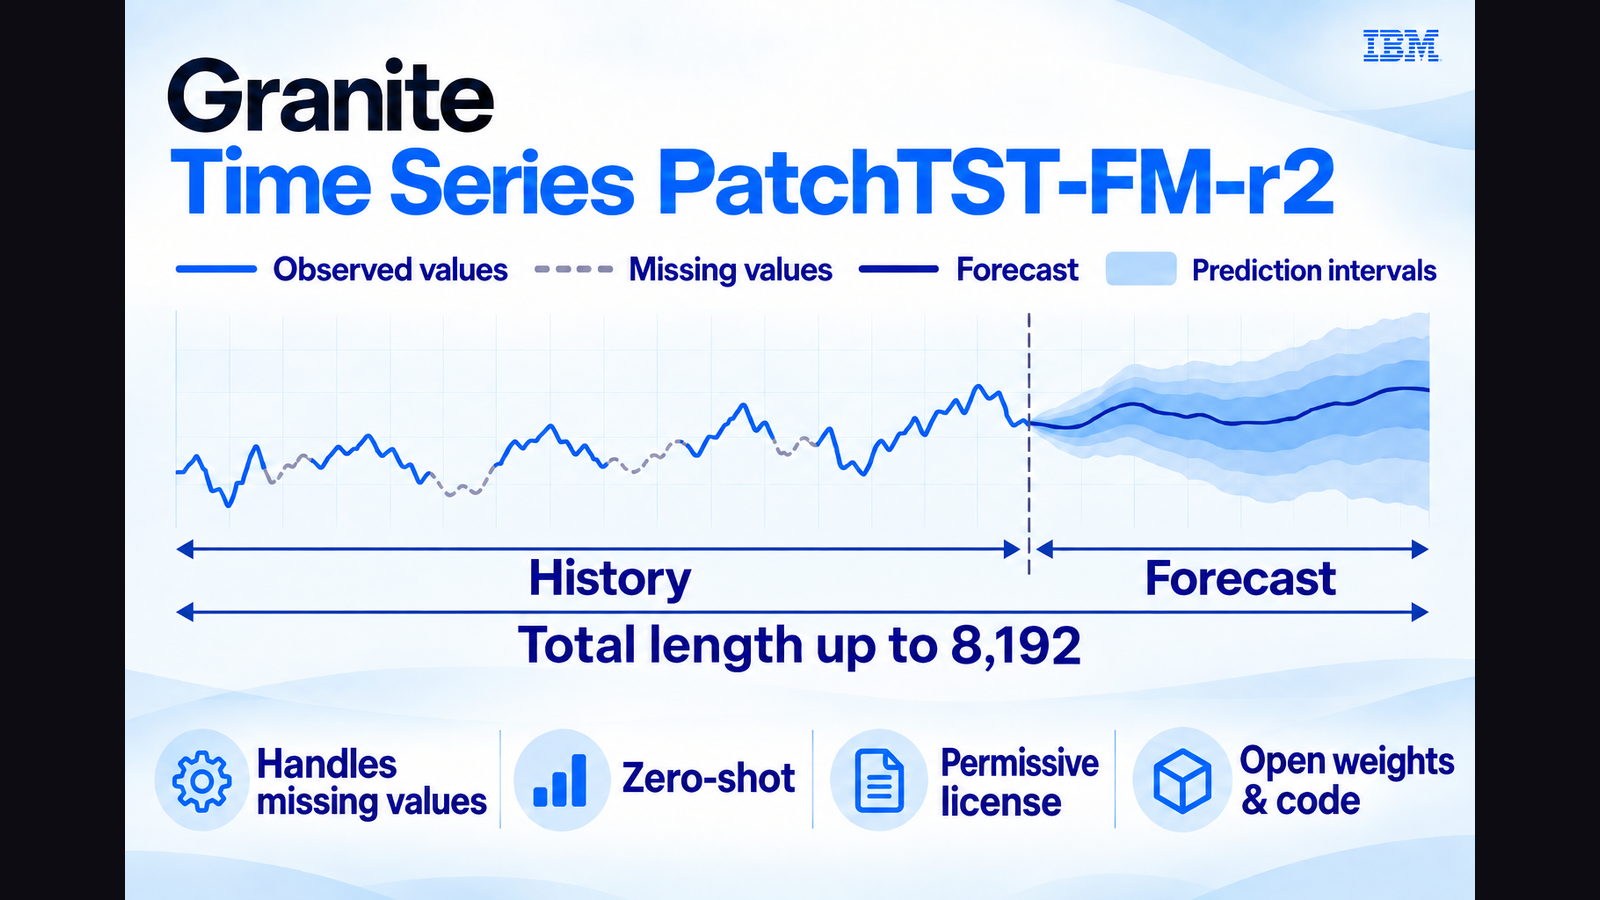
IBM Granite PatchTST-FM-r2 ships open zero-shot time-series forecasting
On Sept. 9, 2026, IBM released Granite Time Series PatchTST-FM-r2, a roughly 385M-parameter zero-shot forecaster with an 8,192-step context and 99-quantile output. IBM reports strong GIFT-Eval standing; MustHave.ai says treat the ranking as company-reported pending benchmark merge.