
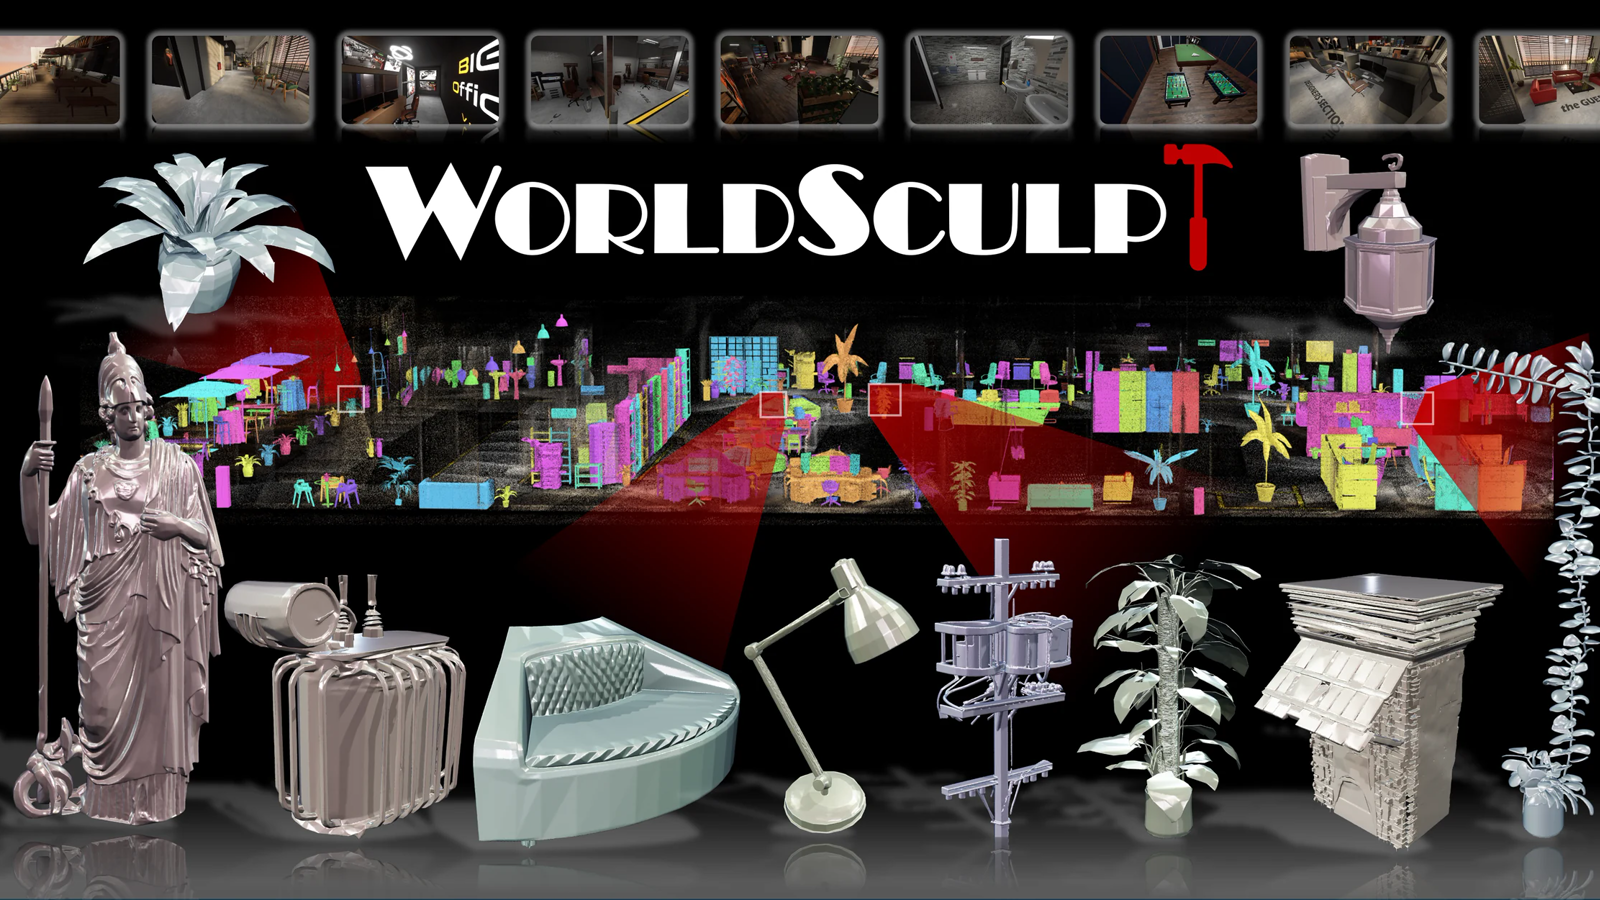
Alaya Lab and the University of Tokyo posted WorldSculpt on Sept. 7, 2026, claiming cluttered multi-view scenes can become hundreds of individually editable object meshes. That editable-parts form is what gaming, AR/VR, simulation and robotics need when a fused mesh or 3D Gaussian soup cannot move object by object.
Unlike scene-level world models such as Marble and HY-World 2.0 that keep a single fused representation, WorldSculpt treats the scene as a collection of addressable object meshes. Given posed RGB images with instance masks and coarse 3D boxes, it places each generated mesh in a shared world frame. Recovering poses, masks and boxes is out of scope.
The method adapts Pixal3D, a TRELLIS.2 structured-latent prior, with a multi-view pathway: per-view DINOv3 features are lifted into an anchor-aligned canonical voxel grid, fused by a permutation-invariant IBR-style aggregator, and injected through zero-initialized layers plus LoRA while the pretrained prior stays frozen except adapters. Authors say the model is finetuned only on single objects in canonical space, yet generalizes at test time to densely occluded scenes with hundreds of objects without scene-level training.
On author tables, WorldSculpt reports HouseCat6D CD-ℓ2 0.28 and F-Score 0.995 versus ShapeR at 1.26 and 0.973, and Toys4k-Scene CD-ℓ2 0.61 and F-Score 0.981 versus ShapeR at 8.38 and 0.746. On UE-MeshyScene, six Unreal Engine 5.8 scenes with 93 to 701 objects each (2,299 objects and 5,964 views at 2560×1440 total), authors report CD-ℓ2 2.48 and F-Score 0.951 versus multi-view ShapeR at 7.42 and 0.813. Under Toys4k stress at 16 views and 75% occlusion, they report CD-ℓ2 2.25 and F@.05 0.929 versus single-view Pixal3D at 63.95 and 0.401. Those Chamfer, EMD and F-Score figures are author claims, not independent replications.
Hugging Face Daily Papers listed the arXiv record on Sept. 7, 2026, and Papers with Code indexes the same paper with related code links. Checkpoints on Hugging Face are marked Apache 2.0 as a finetune of TencentARC/Pixal3D, with code on GitHub. As a qualitative demo, authors apply the same pipeline without extra training to meshify Marble and HY-World 2.0 3DGS worlds via rendered posed views and SAM3 tracking.
Limits stay sharp. Geometry only, no texture or material stage. Static scenes only; moving or deforming objects are unsupported. UE-MeshyScene ground-truth meshes are withheld for copyright, with benchmark evaluation access gated through the project lead. What remains open is independent reproduction of the table metrics, how far upstream pose, mask and box error can go before geometry breaks, and whether texture-stage extensions close the gap to simulation-ready appearance. Author benches and community indexes should be weighed separately until those points are settled.