
Alibaba released Qwen4-Max on Nov. 15, the new top model in its Qwen family of AI models. Alibaba calls it an AI "teammate" for work, creativity and discovery. It reads text, images and video and writes text. Alibaba says it is built for coding, office work, website design and long, complex jobs for AI agents. An AI agent is AI that can carry out tasks on its own, such as using apps and websites, instead of only answering questions. Since Nov. 11, Alibaba has offered a preview version, Qwen4-Max-Preview, only through its Token Plan subscription, and it says that preview will be retired after Nov. 25.
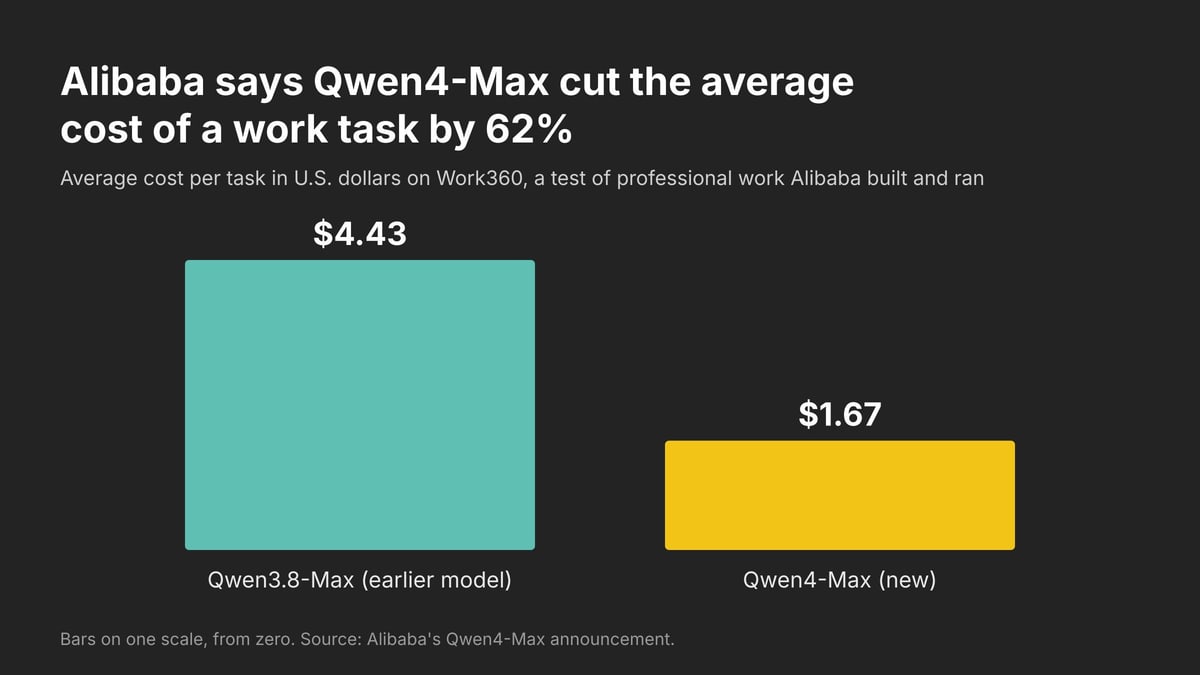
Developers can use Qwen4-Max now through QwenCloud, Alibaba's paid service for its models. Developers can pay through a monthly Token Plan or by the token, the small chunks of text, often parts of words, that AI models read and write. Its Singapore listing prices the model at $1.50 for each million tokens it reads and $4.50 for each million it writes, and a million tokens is about 750,000 English words. People can also use it in QwenStudio, Alibaba's chat app, in Qoder, Alibaba's coding assistant, and in QwenWork. Alibaba's terms for QwenStudio and its other Qwen apps for individual people say they are for adults and for private, non-commercial use only. Alibaba says it lowered prices from Qwen3.8-Max, its last top model, and that the new model scores better than Qwen3.8-Max while using fewer tokens. On Work360, a test of professional tasks Alibaba built itself, Alibaba says the average cost per task fell from $4.43 to $1.67, a 62 percent drop that partly reflects its own price cut.
Alibaba says Qwen4-Max beats Qwen3.8-Max on nearly every skill it tested. Vals AI, an independent company, tests AI models on finance, legal, tax and coding work, and weights each field by its share of the U.S. economy. On its list of 42 models, dated Nov. 18, Qwen4-Max ranks 14th with a score of 63.20 percent, up from 59.05 percent for Qwen3.8-Max, which ranks 21st. Anthropic's Claude Fable 5.2 leads at 71.31 percent, and the 13 models ahead of Qwen4-Max all come from Anthropic, Google, Meta and OpenAI. Vals shows a margin of about a point either way on each score, so Qwen4-Max can't be clearly separated from several models just above and below it, among them OpenAI's GPT-6.1 Sol just ahead and Moonshot AI's Kimi K3.1 Pro just behind. Vals says each of its tests cost $9.33 to run on Qwen4-Max, about half of Claude Fable 5.2's $17.94 but more than double GPT-6.1 Sol's $3.61.
Alibaba says Qwen4-Max's core has 2.4 trillion parameters, the numbers a model tunes as it learns, but uses only 71 billion for each token it handles. It has another 328 billion in a separate part that looks up common patterns of words. It can work with up to 1 million tokens at once. Alibaba says smaller Qwen4 models are coming as open source, which would make them free for anyone to use, study, change and share, but it has not given a date or said exactly what it will release. It has not said the same of Qwen4-Max.
Alibaba's safety checks were run by its own experts. Alibaba says they found no abilities posing large-scale cybersecurity risks, and no sign that the model gives users a significant boost toward chemical, biological, radiological or nuclear weapons. Alibaba also says the model is meant to assist people, not replace professional judgment, and that human expertise and oversight remain essential where decisions carry serious consequences.
Update (Nov. 18): Vals AI updated its list on Nov. 16, adding OpenAI's GPT-6.2 Astra in seventh and GPT-6.2 Sol in ninth. With the same score, Qwen4-Max moved from 11th to 13th.
Update (Nov. 19): Vals updated its list again on Nov. 18, adding Google's Gemini 4 Neon in second place. With the same score, Qwen4-Max is now 14th of 42.